
Your AI security tools are solving yesterday's problem.
Traditional tools evaluate risk one prompt at a time. But your AI isn't a chatbot - it's a stateful agent operating across sessions, tools, and time.



Four threats your current stack can't stop.
Firewalls and DLP were built for stateless requests. Agentic AI is stateful - it reasons across a session, calls tools, and acts on your systems. The risk isn't a bad packet; it's an AI doing something it was never supposed to do.
Prompt injection & jailbreaks
A single crafted input hijacks the model's instructions - exfiltrating data or triggering actions you never authorised. Static filters can't see intent.
Sensitive data leakage
PII, secrets and proprietary context flow into prompts and out through responses - into models and logs you don't control.
Ungoverned tool & MCP actions
Agents call tools, hit APIs and execute MCP actions autonomously. Without a policy gate, one bad decision becomes a real-world action.
Compliance blindness
When the auditor asks what your AI did and why, "we don't log that" isn't an answer. Most stacks have no verifiable record of AI decisions.
A Runtime Governance Layer Built for the AI Era.
VANGUARD is an AI governance platform for managing agentic AI risk and policy enforcement. It sits inline between your applications, models, tools, and workflows to inspect risk, mediate actions, enforce policy, and retain governance evidence. No model changes. No provider lock-in.
Why guardrails aren't governance →Six layers of runtime control. One enforcement point.
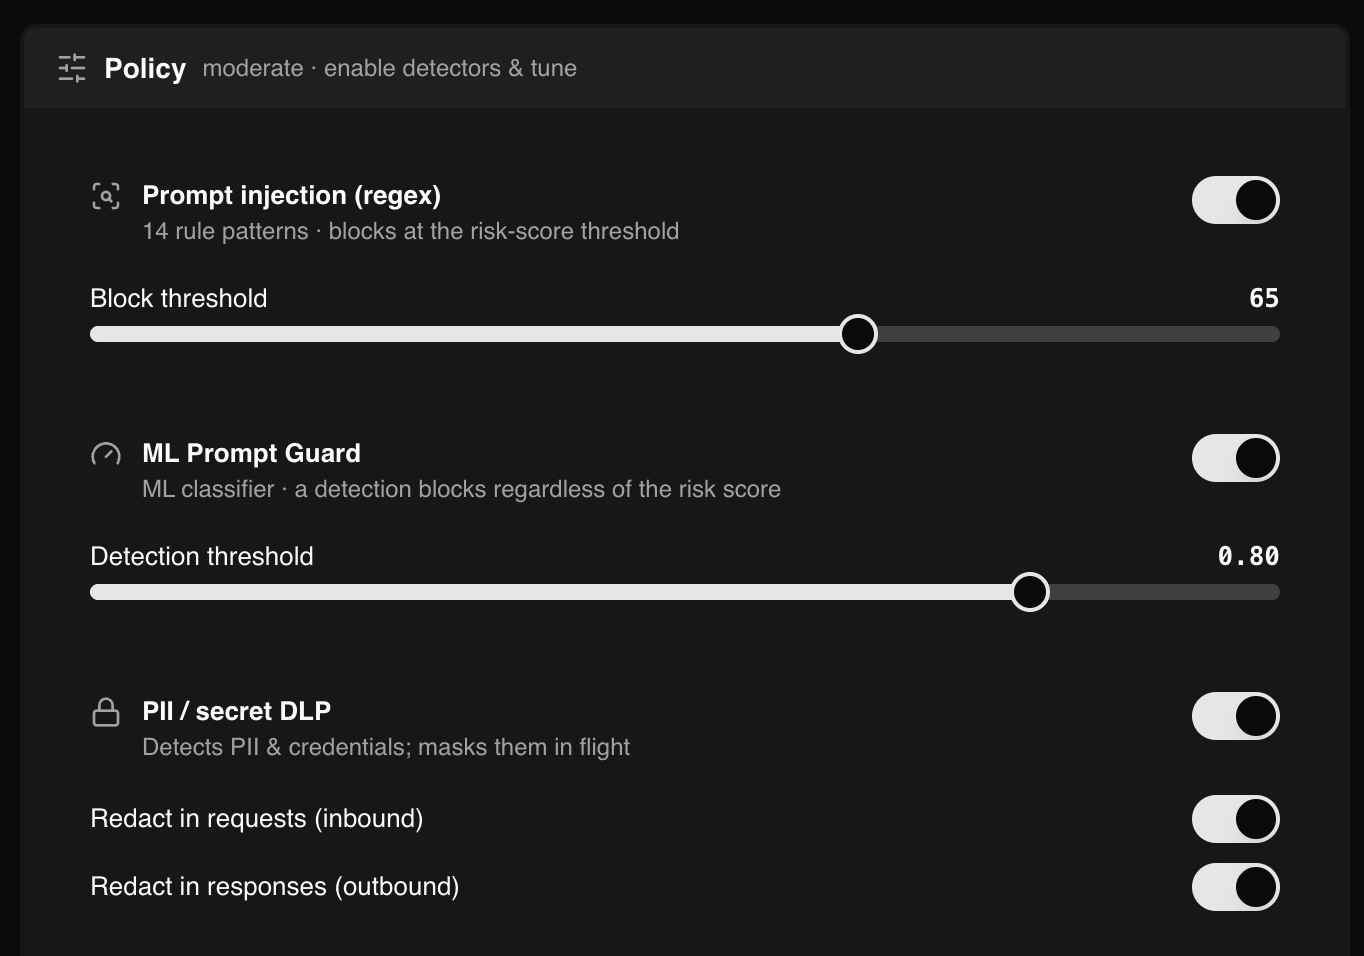
Prompt Injection Detection
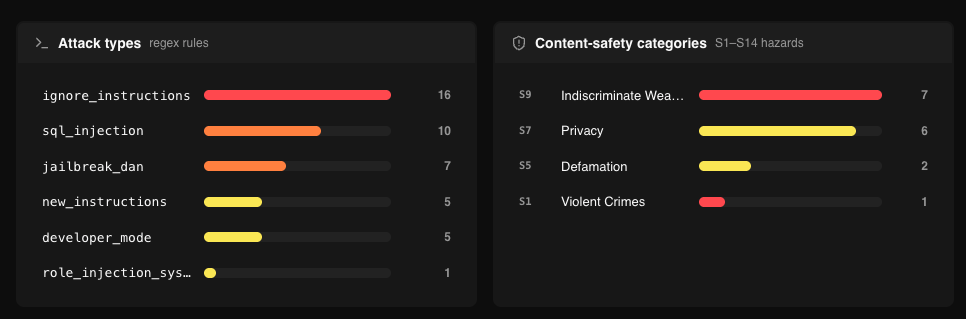
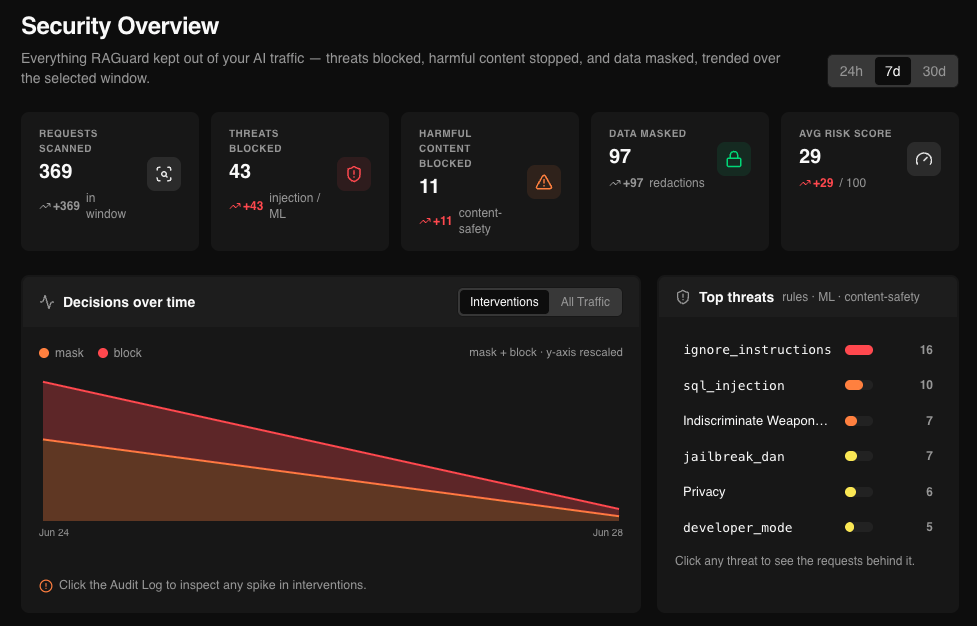
Two-tier detection: fast regex patterns combined with ML classification (Meta Prompt Guard 2). Catches known attack patterns, encoded payloads, and novel injection attempts with configurable confidence thresholds.
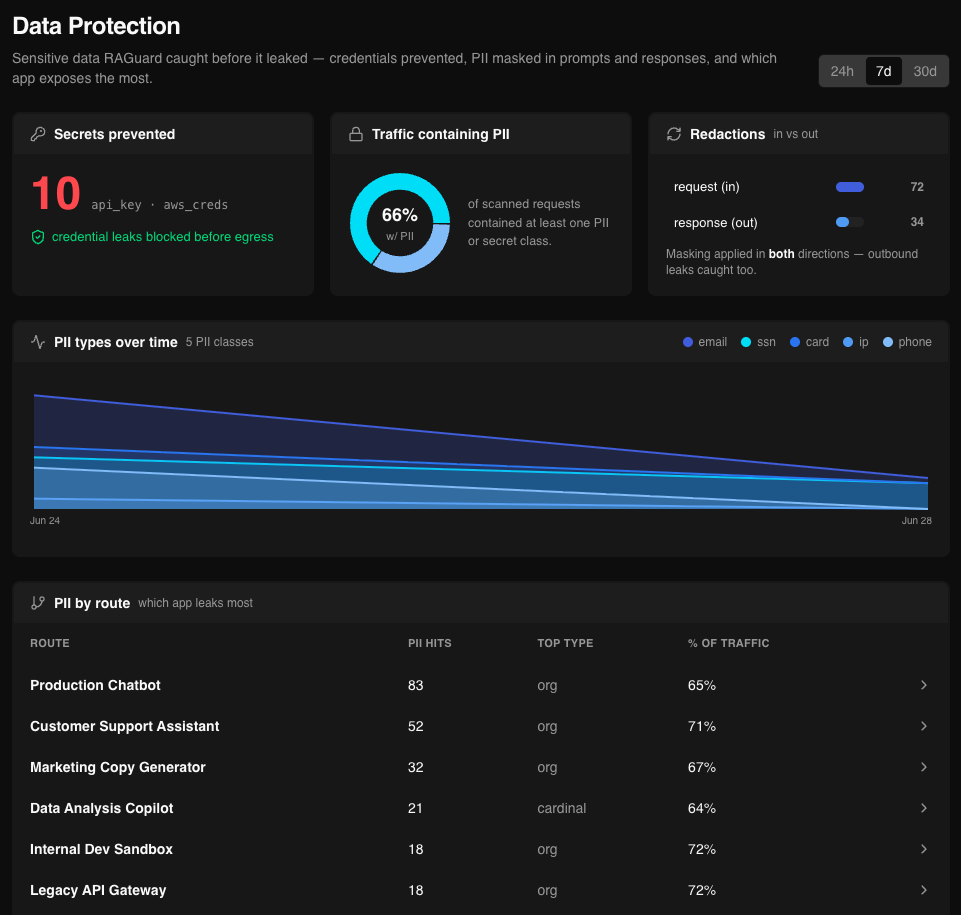
Deep Data Loss Prevention
Named Entity Recognition plus pattern matching detects and redacts PII (emails, SSNs, phone numbers, credit cards), unstructured entities (names, orgs, locations), and secrets (API keys, tokens, credentials).
Content Safety Classification
Identifies harmful content across five categories: hate speech, insults, sexual content, violence, and misconduct. Per-category actions - block, mask, or log - are configurable to your product's risk tolerance.
Output Sanitisation
Post-processing layer catches what the model itself failed to prevent: credential leakage in generated code, hallucinated PII in responses, and policy violations in model outputs before they reach your users.
Policy-as-Code Enforcement
Define granular, tenant-specific rules in Rego using Open Policy Agent (OPA). Control detection thresholds, feature flags, redaction rules, and rate limits. Version-controlled and instantly deployable like any infrastructure policy.
ZKP Audit Trail
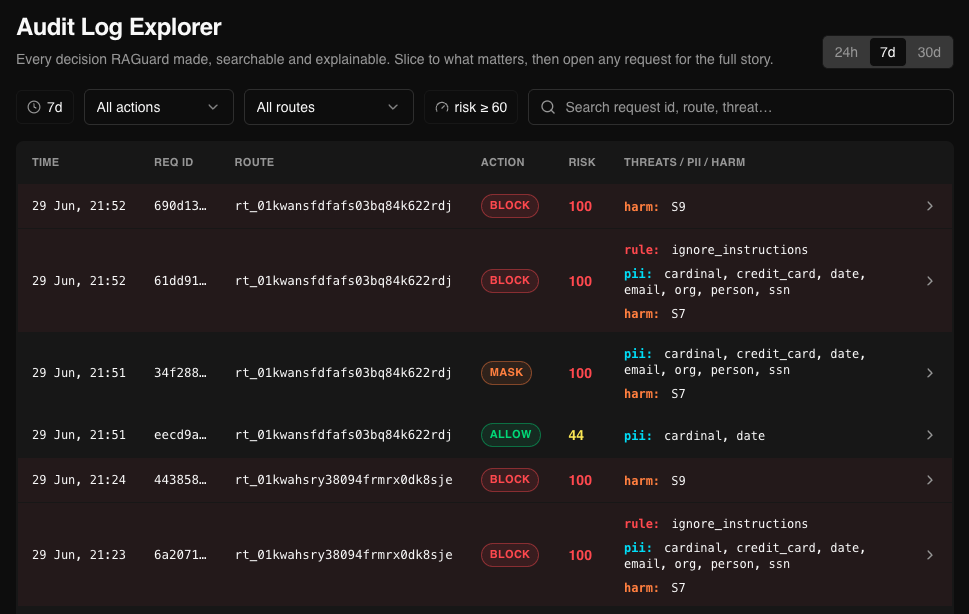
Every interaction is logged with immutable records, risk scores, and Zero-Knowledge Proof-based evidence bundles. Prove compliance to auditors without exposing interaction content. Designed for GDPR, HIPAA, and EU AI Act.
One endpoint change.
Complete protection.
VANGUARD requires no changes to your AI models, no renegotiation of provider contracts, and no infrastructure overhaul. Change one environment variable. Start protecting immediately.
Point your AI calls to VANGUARD
Replace your LLM provider base URL with your VANGUARD proxy endpoint. One environment variable.
Configure your policy
Start with secure-by-default templates or define custom Rego policies for your tenant's risk profile.
Monitor and prove compliance
Every interaction is logged, scored, and cryptographically attested. Your dashboard surfaces threats in real time.
See how VANGUARD stacks up against the alternatives.
VANGUARD vs Lakera
Prompt defence versus runtime governance - governs agent actions, tool calls, and runtime policy.
CompareVANGUARD vs Portkey
AI gateway versus runtime governance - adds governance and trust enforcement above infrastructure.
CompareVANGUARD vs Protect AI
MLSecOps versus runtime governance - focuses on production agent behaviour and runtime controls.
CompareVANGUARD vs Microsoft Prompt Shields
Cloud-native prompt protection versus runtime governance - vendor-neutral and action-oriented across clouds and tools.
CompareVANGUARD vs Gray Swan AI
Red teaming versus runtime governance - enforces policy continuously in production.
CompareVANGUARD vs Akto
API and agent exposure versus runtime governance - governs permissions and runtime execution.
Compare